
A fresh model comparison for coding
The leading candidates changed for coding. Here's what moved and how to compare it with your current setup.
This report compares evidence observed on 2026-10-05 with 2026-10-12. It records changes to our decision guides, not every movement in every leaderboard.
A new release isn't required: newly published tests or revisions can change a comparison. These are changes in the evidence we observed, not proof that a model itself improved.
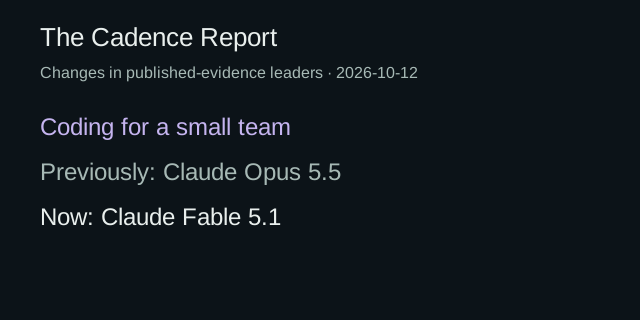
Coding for a small team
The lead moved from Claude Opus 5.5 to Claude Fable 5.1. These are the highest displayed index scores in this mix; tied models share the lead.
The current shared tests don't establish an advantage for Claude Fable 5.1 over Claude Opus 5.5. A change in the overall ranking alone isn't a reason to switch.
Compare a candidate with your current model on a recent bug and a feature that crosses files. Keep the prompts, tools and time budget the same. Check whether the tests pass, how much repair you do, and the actual cost before changing your default.
See the current guide or compare with your model.
What stayed the same
No change in the leading candidates for: Reading and extracting from documents.
Evidence and limits
The chart and downloadable evidence are frozen to this report. Live guide scores can change later. Each guide uses its declared capability weights and the same ranking method as For you. Published test settings and coverage vary; missing results are never filled in.
Download the observed evidence. It includes the previous and current leaders, their test configurations and source links, and the shared-test comparisons.
Reports are checked weekly and published when a guide's leaders change. Quiet weeks have no edition. Follow the reports by RSS or get the weekly email.
This report uses observed evidence snapshots. It suggests what to test, not a guaranteed improvement on your work.